Our Thoughts
On-Premise AI Has a Trust Problem. Here's How We Fixed It
October 19, 2026
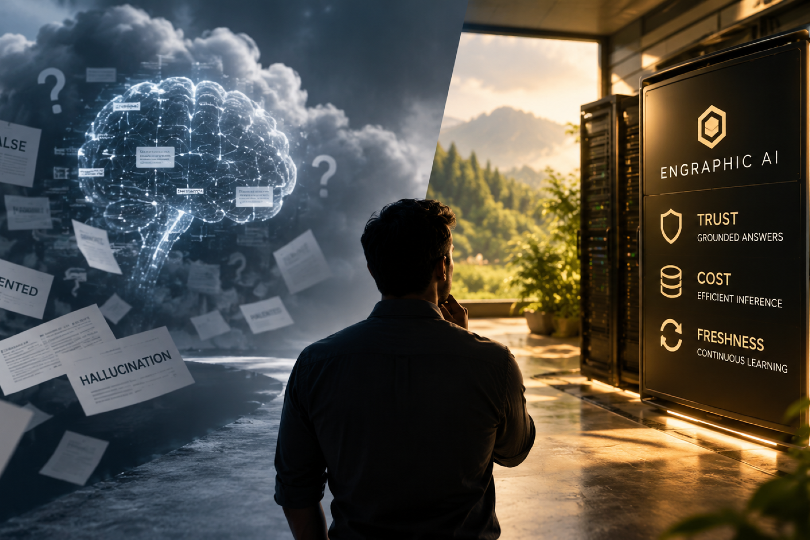
Most of the on-premise AI conversation is stuck on the wrong question. Teams debate "cloud or on-prem?" as if location were the whole decision. It isn't. Moving a model onto your own servers protects your data — and then leaves two problems completely untouched.
Here's the part nobody selling you a server rack wants to dwell on: putting a model on-premise changes where it runs, not how it reasons. A model that confidently fabricates an answer in the cloud will fabricate that same answer just as confidently on hardware you own. And the conventional recipe for running it — a rack of data-center GPUs with the power and cooling to match — costs enough that most organizations quietly give up and go back to the cloud.
So the real on-premise question isn't about location at all. It's two questions: Can I trust what the model tells me? And can I actually afford to run it? We built Engraphic AI to answer both with a yes.
The shift nobody's pricing in
For the last few years the entire industry has organized itself around a single assumption: that the frontier is about training ever-larger models, and that doing so requires tens of billions of dollars and a hyperscaler's data center. That assumption shaped where the money went, where the talent went, and where your data ended up — sitting on someone else's servers, metered by the token.
But the value is quietly migrating. Training a model is a one-time event. Running it — grounding it in real data, keeping it current, answering millions of real queries — is forever. And the economics of running a model look nothing like the economics of training one. This is where the incentives of the big cloud providers and the interests of their customers come apart: a business that pays per token for continuous AI is a business whose costs scale with its own success.
On-premise AI is the natural endpoint of that shift. When AI becomes daily infrastructure rather than an occasional API call, owning the thing that runs it stops being exotic and starts being obvious.
The only reason more organizations haven't made the move is that the two problems above — trust and cost — have stood in the way. So let's talk about how Engraphic removes them.
How Engraphic AI works
Engraphic is an on-premise AI platform built on three pillars. Each one targets a specific failure of the conventional approach.
Pillar 01 — Trust
Grounding, so the model reports instead of inventing
A standard language model generates the most plausible continuation of your prompt. Plausible is not the same as true — which is why these models hallucinate. Engraphic's grounding architecture inverts that: every answer is tied back to source material, and the system is built to report what the records actually support rather than to fill gaps with confident-sounding text.
The result is measurable. In benchmark testing, an Engraphic deployment returned zero fabrications across 969 queries run against 143 million medical records. For fiduciary-grade work — a diagnosis, a legal citation, an engineering tolerance — that distinction between "plausible" and "supported" is the entire ballgame. An unsupported answer isn't a minor error; it's a liability.
Pillar 02 — Cost
Efficient inference, so you don't need a GPU farm
The reason on-premise AI has a reputation for being expensive is that the industry assumes you need stacks of high-end data-center GPUs to run a capable model. Engraphic was engineered from a different starting point. Instead of throwing more silicon at the problem, it treats fast local storage as an active part of the compute fabric — pulling capable models through compact, prosumer-class hardware at a fraction of the power a GPU cluster draws.
That single design decision collapses both halves of the cost: the upfront capital to buy the machine, and the ongoing power bill to keep it running. It's what makes sovereign, private AI realistic for a clinic, a law firm, or a government office — not just for the handful of organizations that can afford to build a data center.
Pillar 03 — Freshness
Continuous learning, so the model doesn't go stale
Almost every deployed model is frozen the day it ships. It only improves when the vendor retrains it centrally — which means sending your data back out, or waiting for a generic update that knows nothing about your work. Engraphic's architecture supports continuous learning: the model keeps adapting to your data, your terminology, and your workflows after it's installed, and every bit of that adaptation stays inside your walls.
Over time, an Engraphic deployment becomes more yours, not less — the opposite of a cloud model that treats every customer as interchangeable.
What this makes possible
Put the three pillars together and you get something the cloud structurally cannot offer: an AI system that is private by physics, grounded in your own verified sources, affordable to run continuously, and improving on your data without any of it leaving the building.
That combination matters most in the places where getting it wrong is expensive:
- Healthcare — clinical decision support that stays compliant and never fabricates.
- Legal & professional services — fiduciary-grade research grounded in authoritative sources, kept entirely in-house.
- Government & sovereign deployments — AI free of foreign or third-party dependencies, where the data and the decisions stay within the jurisdiction.
- Engineering & industrial operations — proprietary technical knowledge that can't be exposed to an outside API.
We call this fiduciary-grade AI, because the standard it has to meet is the one a professional is held to: not "usually right," but accountable — grounded, auditable, and under your control.
The bottom line
On-premise AI was never really about the server room. It's about whether you can trust the answers, afford to run them, and keep the whole thing yours. For a long time you had to pick two. Engraphic AI exists so you don't have to.
Engraphic AI
Engraphic AI builds grounded, continuously learning AI that runs on hardware you own — private and sovereign by design. Co-founded by Tim and Chase Sutherland.
See it on your own data
Grounded answers, sovereign data, continuous learning, hardware you can afford. Let's talk about what Engraphic AI looks like in your environment.